Make a distribution object by specifying properties (e.g., cdf, density, mean, etc.). Some properties, if not included, will be calculated based on other properties that are included (e.g., quantile from cdf; variance from standard deviation). A list of these representations can be found in the details.
Usage
distribution(
  ...,
  .support = NULL,
  .vtype = NULL,
  .name = NULL,
  .parameters = list()
)

is_distribution(object)

is.distribution(object)
Arguments
- ...
Name-value pairs for defining the distribution.
- .support
Required. Where the distribution places probability, built with
discrete(),continuous()ormixed(). A barediscretesobject is also accepted, and treated asdiscrete(). See Details.- .vtype
 Removed in favour of
.support, and now an error. See Details.- .name
A name to give to the distribution. Can be any character vector of length 1.
- .parameters
A named list with one entry per distribution parameter, each of which can be any data type. In this version of distionary, these parameters are only stored for the benefit of the user to know what distribution they are working with; the code never looks at these parameters to inform its calculations. This is anticipated to change in a future version of distionary.
- object
Object to be tested
Details
The support
Every distribution has to say where it places probability, and .support
is how. It is the one thing distionary asks for rather than working out: a
CDF does hold the answer, its jumps being the atoms and its flattening out
marking where the distribution ends, but recovering that numerically means
hunting for discontinuities in a function that can only be sampled. The
estimate would be worst for small atoms and long tails, which are the cases
where it matters most.
Declared instead, it is exact, and the difference shows: quantiles at probability 0 and 1 are read off rather than searched for in the numerical tail, atoms are located exactly, and moments can be decomposed. It is the same bargain as declaring atoms — a little more to say up front, in exchange for exact answers rather than approximate ones. The "The Support of a Distribution" vignette covers what a support is and how to build one.
The variable type (vtype()) and the range() follow from the support, so
neither can be given here; see the property list below.
.vtype used to take a string such as "continuous" and is now defunct. A
variable type cannot stand in for a support: "discrete" does not say
which points carry mass, and "continuous" does not say over what
region, so there is no translating one into the other, and a guess would be
quietly wrong rather than an error. The argument is kept only so that old
code gets a message saying what to do, rather than unused argument.
Properties
Currently, the CDF (cdf) is required to be specified, along with the PMF
(pmf) for discrete distributions and density (density) for continuous
distributions. Otherwise, the full extent of distribution properties will
not be accessible.
A distributional representation is a function that fully describes the
distribution. Besides cdf, density, and pmf, other options
understood by distionary include:
survival: the survival function, or one minus the cdf.hazard: the hazard function, for continuous variables only.chf: the cumulative hazard function, for continuous variables only.quantile: the quantile function, or left-inverse of the cdf.realiseorrealize: a function that takes an integer and generates a vector of that many random draws from the distribution.odds: for discrete variables, the probability odds function (pmf / (1 - pmf))return: the quantiles associated with the provided return periods, where events are exceedances.
All functions should be vectorized.
Other properties that are understood by distionary include:
mean,stdev,variance,skewness,medianare self-explanatory.kurtosis_excandkurtosisare the distribution's excess kurtosis and regular kurtosis.
range and vtype are properties too, and eval_property() reads them
like any other, but they cannot be given here: the support determines both,
and a stated one could disagree with it. A name distionary does not know is
simply kept, retrievable with eval_property() and otherwise unused.
Examples
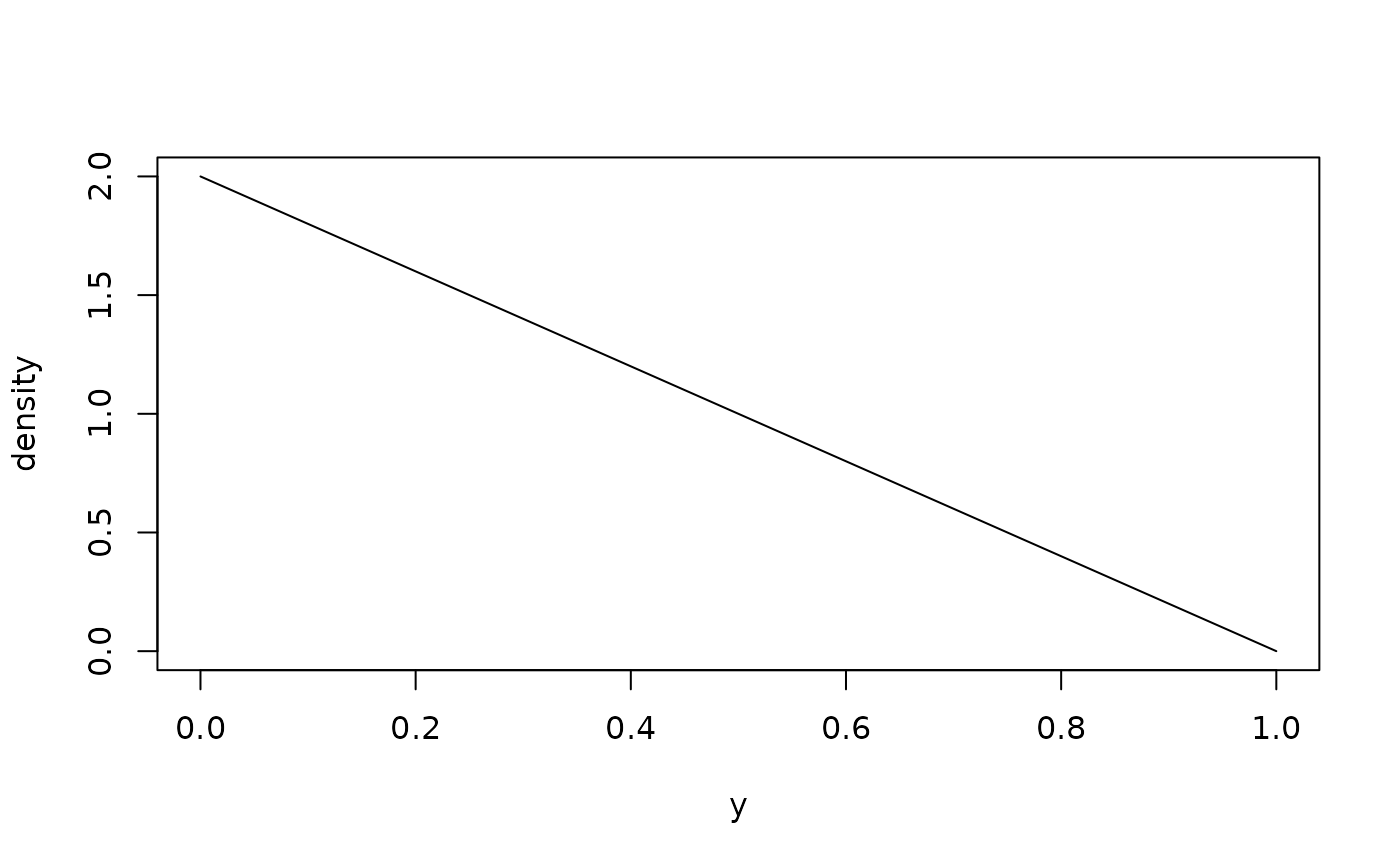
linear <- distribution(
  density = function(x) {
    d <- 2 * (1 - x)
    d[x < 0 | x > 1] <- 0
    d
  },
  cdf = function(x) {
    p <- 2 * x * (1 - x / 2)
    p[x < 0] <- 0
    p[x > 1] <- 1
    p
  },
  .support = continuous(c(0, 1)),
  .name = "My Linear",
  .parameters = list(could = "include", anything = data.frame(x = 1:10))
)

# Inspect
linear
#> My Linear distribution (continuous)
#> --Parameters--
#> $could
#> [1] "include"
#>
#> $anything
#>     x
#> 1   1
#> 2   2
#> 3   3
#> 4   4
#> 5   5
#> 6   6
#> 7   7
#> 8   8
#> 9   9
#> 10 10
#>

# Plot
plot(linear)